DeepSeek V4 Pro Stays Available — the 9/14 V4.1 Flash Routing Notice Is Withdrawn
When DeepSeek released DeepSeek-V4.1-Flash on 2026-09-10, it also announced that it would retire V4 Pro in an orderly manner and route all deepseek-v4-pro requests to V4.1 Flash from 2026-09-14.
DeepSeek has since reversed that notice. The company now states that it will continue serving the V4 Pro API after 2026-09-14 with the billing method unchanged.
This page documents the current status, pricing and specifications, the history of the reversal, and how to choose between V4 Pro and V4.1 Flash, using only DeepSeek's own official documentation.
For the full V4.1 Flash guide (pricing, specs, benchmarks, setup), see the DeepSeek V4.1 Flash guide.
✅ Bottom line (3 points)
deepseek-v4-prokeeps working after 2026-09-14. DeepSeek states: "In response to user demand, we have decided to continue providing API services for DeepSeek V4 Pro after September 14, 2026, with the billing method remaining unchanged."- V4 Pro keeps its own separate rate card. The official pricing page still lists a dedicated V4 Pro row — it was not consolidated into V4.1 Flash pricing (off-peak input $0.66 / output $1.98).
- The "everything routes to V4.1 Flash at the Flash price from 13:00 JST on 2026-09-14" notice has been withdrawn. DeepSeek nonetheless says it "will provide further notice should there be any changes," so future changes are not impossible.
→ For the cheaper, vision-capable sibling, see the DeepSeek V4.1 Flash guide.
【Important】Correction to our earlier coverage, and what DeepSeek withdrew
What was withdrawn
Until 2026-09-11, this page (and other pages on this site) stated that
"from 13:00 JST on 2026-09-14 (12:00 Beijing time / 04:00 UTC), and until V4.1 Pro is released, all requests to deepseek-v4-pro are routed to V4.1 Flash and billed at the V4.1 Flash price."
That statement has been withdrawn by DeepSeek and is no longer correct.
At the time, DeepSeek said V4.1 Flash "has comprehensively surpassed V4 Pro in performance, cost, speed, and total time, so we plan to retire V4 Pro in an orderly manner." Since then, both footnote (2) of the official pricing page and the Change Log (2026-09-10 entry) have been replaced with the following (verbatim):
"In response to user demand, we have decided to continue providing API services for DeepSeek V4 Pro after September 14, 2026, with the billing method remaining unchanged. We will provide further notice should there be any changes."
In other words, as of 2026-09-13 there is no retirement schedule and no 9/14 routing in the official documentation. We have rewritten this page to reflect the reversal (last updated 2026-09-13). Note that third-party round-ups still describe V4 Pro as retiring, and the 9/11 notice is still quoted in places — as of 2026-09-13 the official primary source says V4 Pro continues.
Note on wording: DeepSeek does not itself use the word "withdrawn". The official text now states that, in response to user demand, API services for DeepSeek V4 Pro will continue after September 14, 2026 with the billing method unchanged. We describe the earlier routing notice as withdrawn because it is no longer present in the current official documentation (pricing-page footnote (2) and the Change Log). DeepSeek says it will provide further notice of any changes, so check the official pages for the latest status.
Current status (as documented on 2026-09-13)
| Item | Current state |
|---|---|
| API model name | deepseek-v4-pro (model version DeepSeek-V4-Pro-0813) |
| Availability | Live. Continues after 2026-09-14 with billing unchanged (official footnote (2)) |
| Base URLs | https://api.deepseek.com (OpenAI format) / https://api.deepseek.com/anthropic (Anthropic format). Shared with V4.1 Flash |
| Context / max output | 1M / 384K (same as V4.1 Flash) |
| Thinking mode | Both non-thinking and thinking (default). Thinking effort supports three levels — low / high / max (per the 2026-08-13 GA announcement) |
| Features | JSON Output ✓ / Tool Calls ✓ / Responses API ✓ / Anthropic API ✓ / Chat Prefix Completion (Beta) ✓ / FIM Completion (Beta) non-thinking mode only |
| Vision (image input) | Not supported (V4.1 Flash supports it natively) |
| Concurrency limit | 500 (V4.1 Flash is 2500) |
| Azure / Microsoft Foundry | Azure also sells DeepSeek-V4-Pro directly (input 1M / output 384K / tool calling supported) |
Sources: Models & Pricing · Change Log (2026-08-13 / 2026-09-10). Azure: Microsoft Learn — Foundry Models sold by Azure.
V4 Pro current rates (in effect as of 2026-09-13)
| Item | Off-peak | Peak |
|---|---|---|
| Input (cache miss) | $0.66 | $1.32 |
| Input (cache hit) | $0.022 | $0.044 |
| Output | $1.98 | $3.96 |
Effective 2026-08-16 16:00 UTC. Peak hours are 01:00-04:00 and 06:00-10:00 UTC on weekdays (JST Mon-Fri 10:00-13:00 / 15:00-19:00); weekends are off-peak all day. Off-peak is half the peak rate. The old promo rates ($0.435/$0.87) are retired. For the cheaper option see the V4.1 Flash rate card. Source: api-docs.deepseek.com (retrieved 2026-09-13).
V4 Pro vs V4.1 Flash — differences and how to choose
| Item | V4 Pro (deepseek-v4-pro) | V4.1 Flash (deepseek-flash) |
|---|---|---|
| Availability | Live (continuing) | Live (released 2026-09-10) |
| Input (cache miss) | $0.66 / $1.32 (off / peak) | $0.15 / $0.30 (off / peak) |
| Input (cache hit) | $0.022 / $0.044 | $0.003 / $0.006 |
| Output | $1.98 / $3.96 | $0.60 / $1.20 |
| Context / max output | 1M / 384K | 1M / 384K |
| Vision (image input) | Not supported | Native support ✓ |
| Concurrency limit | 500 | 2500 |
| Best fit | Workloads where reasoning depth and agentic quality matter (GA benchmarks: HLE 42.7 / 60.0 with tools, Terminal Bench 2.1 87.9, DeepSWE 62.7) | Cost, speed and throughput; image input; large batches |
💡 Rule of thumb: with an identical 1M context and 384K output, the differences are price, vision support, concurrency limit and reasoning depth. Batch or image-bearing workloads favour V4.1 Flash; deep reasoning or complex agent work favours V4 Pro. Note that DeepSeek's earlier claim that V4.1 Flash outperforms V4 Pro was part of the notice that has now been replaced, so the current official pages no longer carry that comparison. Measure on your own representative prompts. Use the token calculator to compare both models across both time windows.
How we got here (based on official announcements)
- 2026-04-24 — DeepSeek V4 (V4-Pro / V4-Flash) launches on the API. Legacy names
deepseek-chat/deepseek-reasonerenter a migration window. - 2026-07-24 — Legacy aliases
deepseek-chat/deepseek-reasonerare discontinued. - 2026-07-31 — V4-Flash reaches GA as
V4-Flash-0731. - 2026-08-13 — V4-Pro (-0813 / GA) ships. Much stronger agent capabilities, native Responses API support, and three thinking-effort levels (low / high / max). Peak/off-peak pricing announced.
- 2026-08-16 16:00 UTC — All V4 models move to peak/off-peak billing (off-peak is half the peak rate).
- 2026-08-21 — Experimental
deepseek-v4-flash-vision-expbecomes available. - 2026-09-10 — DeepSeek-V4.1-Flash is released. V4 Flash and V4 Flash Vision Exp are retired and folded into V4.1 Flash. The same announcement says V4 Pro will be retired in an orderly manner and routed to V4.1 Flash from 9/14.
- Between 2026-09-11 and 09-13 — DeepSeek reverses that notice. Footnote (2) of the pricing page and the Change Log are replaced with "we will continue providing API services for DeepSeek V4 Pro after September 14, 2026, with the billing method remaining unchanged." The V4 Pro pricing row is retained.
- 2026-09-13 (today) —
deepseek-v4-prois live. No retirement or routing is scheduled.
Source: DeepSeek Change Log. See also the release timeline.
What to check right now (checklist)
- Inventory your model names.
deepseek-v4-prokeeps working — no rewrite needed. Switch todeepseek-flashonly if you want the cheaper option. - Look for retired names.
deepseek-v4-flash,deepseek-v4-flash-vision-exp,deepseek-chatanddeepseek-reasonerare retired or discontinued; those requests are served by V4.1 Flash at the Flash price. - Update any internal notes or estimates built on the 9/11 notice. Any cost model that assumed "Flash pricing from 9/14" now rests on a broken premise — V4 Pro stays at $0.66 (off-peak input) / $1.98 (off-peak output).
- Need image input? Use V4.1 Flash. V4 Pro has no vision support.
- Refresh your cost estimate. The token calculator covers both models across off-peak and peak.
- Shift work off-peak where you can. Peak is 10:00-13:00 and 15:00-19:00 JST on weekdays (2× rate); weekends are off-peak all day.
Setup in VS Code GitHub Copilot Chat (3 steps)
Recorded by the operator (okamo channel) during an actual setup. Extension labels and the model picker may change over time.
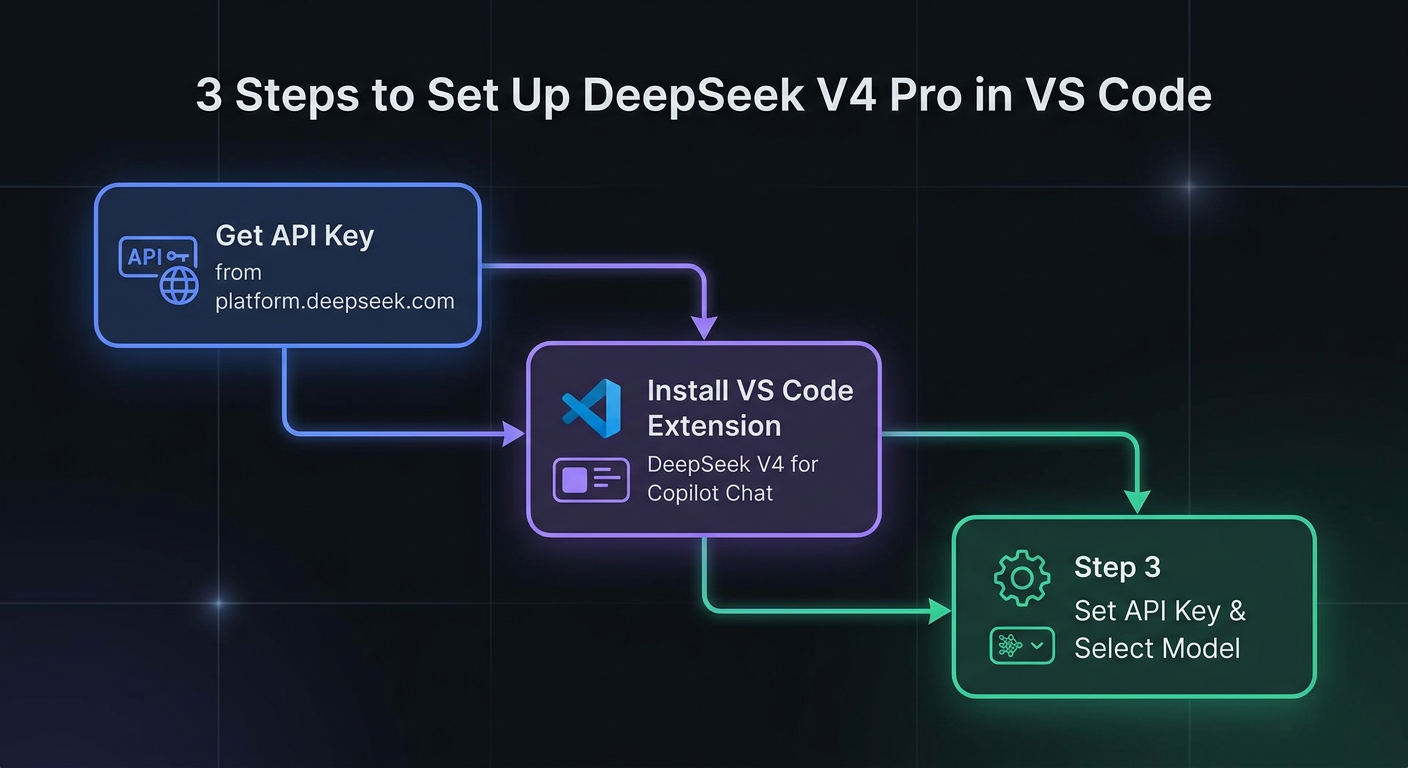
ℹ️ This figure records the setup as of 2026-07 and shows deepseek-v4-pro in the configuration example. V4 Pro is a currently supported model, so that label is not an error (as of 2026-09-13). For image input you can also pick deepseek-flash (V4.1 Flash). Extension labels may change.
Get an API key
Register at platform.deepseek.com. Top up via PayPal or credit card (VISA/Mastercard) and issue an API key starting with sk-. Fully prepaid, $2 minimum top-up, no auto-recharge.
Install the extension
Install DeepSeek V4 for Copilot Chat (publisher: Vizards) from the VS Code Marketplace.
Configure and start
Open the command palette (Cmd/Ctrl+Shift+P) → DeepSeek: Set API Key and register the key. Pick a DeepSeek V4 model in the Copilot Chat model picker to start chatting.
Source: operator's setup record (2026-07-04). For current pricing and specs see the V4.1 Flash guide.
Reference: V4 Pro vs Claude Sonnet in practice (historical note)
In the operator's hands-on experience at the time, V4 Pro delivered near-Claude-Sonnet practical quality on text-centric coding tasks at a much lower cost. The comparison was not a strict like-for-like test, however: the Sonnet side covered two roles (coordinator plus a hard-nosed engineer) while the DeepSeek side covered one.
An earlier version of this page cited a measured cost example of "Claude Sonnet $5.33 vs DeepSeek V4 Pro $0.26 (about 95% cheaper)". That figure was measured under the old promo pricing ($0.435/$0.87) and does not carry over to current V4 Pro rates (output $1.98 off-peak), so we removed it. For current comparisons use the token calculator and the pricing page.
Original reports: savings-mode comparison / Claude vs DeepSeek code-review comparison
FAQ
Q. What happens to V4 Pro after September 14?
A. It keeps running. DeepSeek states that, in response to user demand, it will continue providing API services for DeepSeek V4 Pro after September 14, 2026, with billing unchanged, and will give further notice if anything changes. The previously announced "routes to V4.1 Flash from 9/14" plan was withdrawn.
Q. What does "billing method remaining unchanged" actually mean?
A. It means V4 Pro was not folded into V4.1 Flash pricing — V4 Pro's own rate structure continues. The official pricing page still carries a dedicated V4 Pro row (cache hit $0.022/$0.044, cache miss $0.66/$1.32, output $1.98/$3.96), separate from the V4.1 Flash rates ($0.15/$0.30, $0.003/$0.006, $0.60/$1.20).
Q. Do I need to change my code or API key?
A. No. Code that specifies deepseek-v4-pro keeps working. In fact, because of the reversal, any migration you performed on the assumption of the 9/11 notice may now be unnecessary. Moving to V4.1 Flash can still make sense on price, speed and vision support.
Q. Is V4 Pro pricing still valid?
A. Yes. Cache-miss input $0.66 off-peak / $1.32 peak, cache-hit input $0.022 / $0.044, output $1.98 off-peak / $3.96 peak, in USD per 1M tokens. Our previous "reference values valid only through 2026-09-13" wording was wrong and has been corrected.
Q. So which should I use — V4 Pro or V4.1 Flash?
A. DeepSeek's 2026-09-10 announcement claimed V4.1 Flash beats V4 Pro on performance, cost, speed and total time, but that text was part of the notice that has now been replaced, and the current official pages no longer carry the comparison. Context (1M) and max output (384K) are identical, so the decision rests on price, vision support, concurrency and reasoning depth. Use V4.1 Flash for image-bearing or high-volume work; benchmark V4 Pro where deeper reasoning pays off.
Q. Could the notice change again?
A. Yes. DeepSeek explicitly says it "will provide further notice should there be any changes." We keep checking the official pricing page and Change Log and will update this page if anything moves.
Q. Does V4 Pro support images?
A. No. The official feature table marks Vision as "Not supported" for V4 Pro. Use V4.1 Flash for image input. See the multimodal LLM guide for image, audio, video and PDF support across providers.
Sources
- DeepSeek API Docs — Models & Pricing (retrieved 2026-09-13; footnote (2) confirms V4 Pro continues, and the V4 Pro pricing row is still listed)
- DeepSeek API Docs — Change Log (the 2026-09-10 entry now includes the V4 Pro continuation; the 2026-08-13 entry covers V4-Pro GA)
- Microsoft Learn — Foundry Models sold by Azure (Azure lists DeepSeek-V4-Pro; retrieved 2026-09-13)
- Related: DeepSeek V4.1 Flash guide · pricing (DeepSeek) · token calculator · release timeline
⚠️ Disclaimer
- This page is based on the official pricing page and Change Log at api-docs.deepseek.com as retrieved on 2026-09-13. Pricing and model availability can change without notice. Always verify on the official pages before contracting or running production workloads.
- Until 2026-09-11 this page stated that requests to
deepseek-v4-prowould route to V4.1 Flash and be billed at the Flash price from 2026-09-14. That announcement was withdrawn by DeepSeek, so we have corrected the page. - The retired "2026-09-14 13:00 JST" timestamp shown in the previous version was our conversion of DeepSeek's then-current "12:00 Beijing time on 2026-09-14". No such schedule currently exists.
- Hands-on notes reflect the operator's own environment and workload and do not guarantee the same results elsewhere. The Claude Sonnet comparison in particular covered different task compositions, so it was not a strict like-for-like test.
- This site does not endorse or represent any provider. DeepSeek is a trademark of DeepSeek. GitHub and GitHub Copilot are trademarks or registered trademarks of GitHub, Inc.